Ask an LLM for "a complete architecture" in one prompt and the output looks entirely reasonable:
/pages
  /dashboard.js
  /settings.js
/components
  /Sidebar.js
  /ProjectCard.js
/db/schema.sql
Copy that into a fresh repo, try to run it, and three problems surface within about a minute.
Imports point at nothing. ProjectCard.js imports useProjects from /hooks/useProjects.ts, which was never generated.
Components got reinvented. There is a <Sidebar /> on the dashboard and a <NavBar /> on settings. Same UI element, designed twice, independently.
The schema is decorative. It defines a projects table with a status column that nothing in the UI ever reads or writes. It was assumed and never connected.
None of these are model failures. They are the consequence of asking for architecture before the artifacts it should be derived from exist. Architecture is downstream of stories, features, and data. Starting with the file tree is starting at the end.
The correct ordering
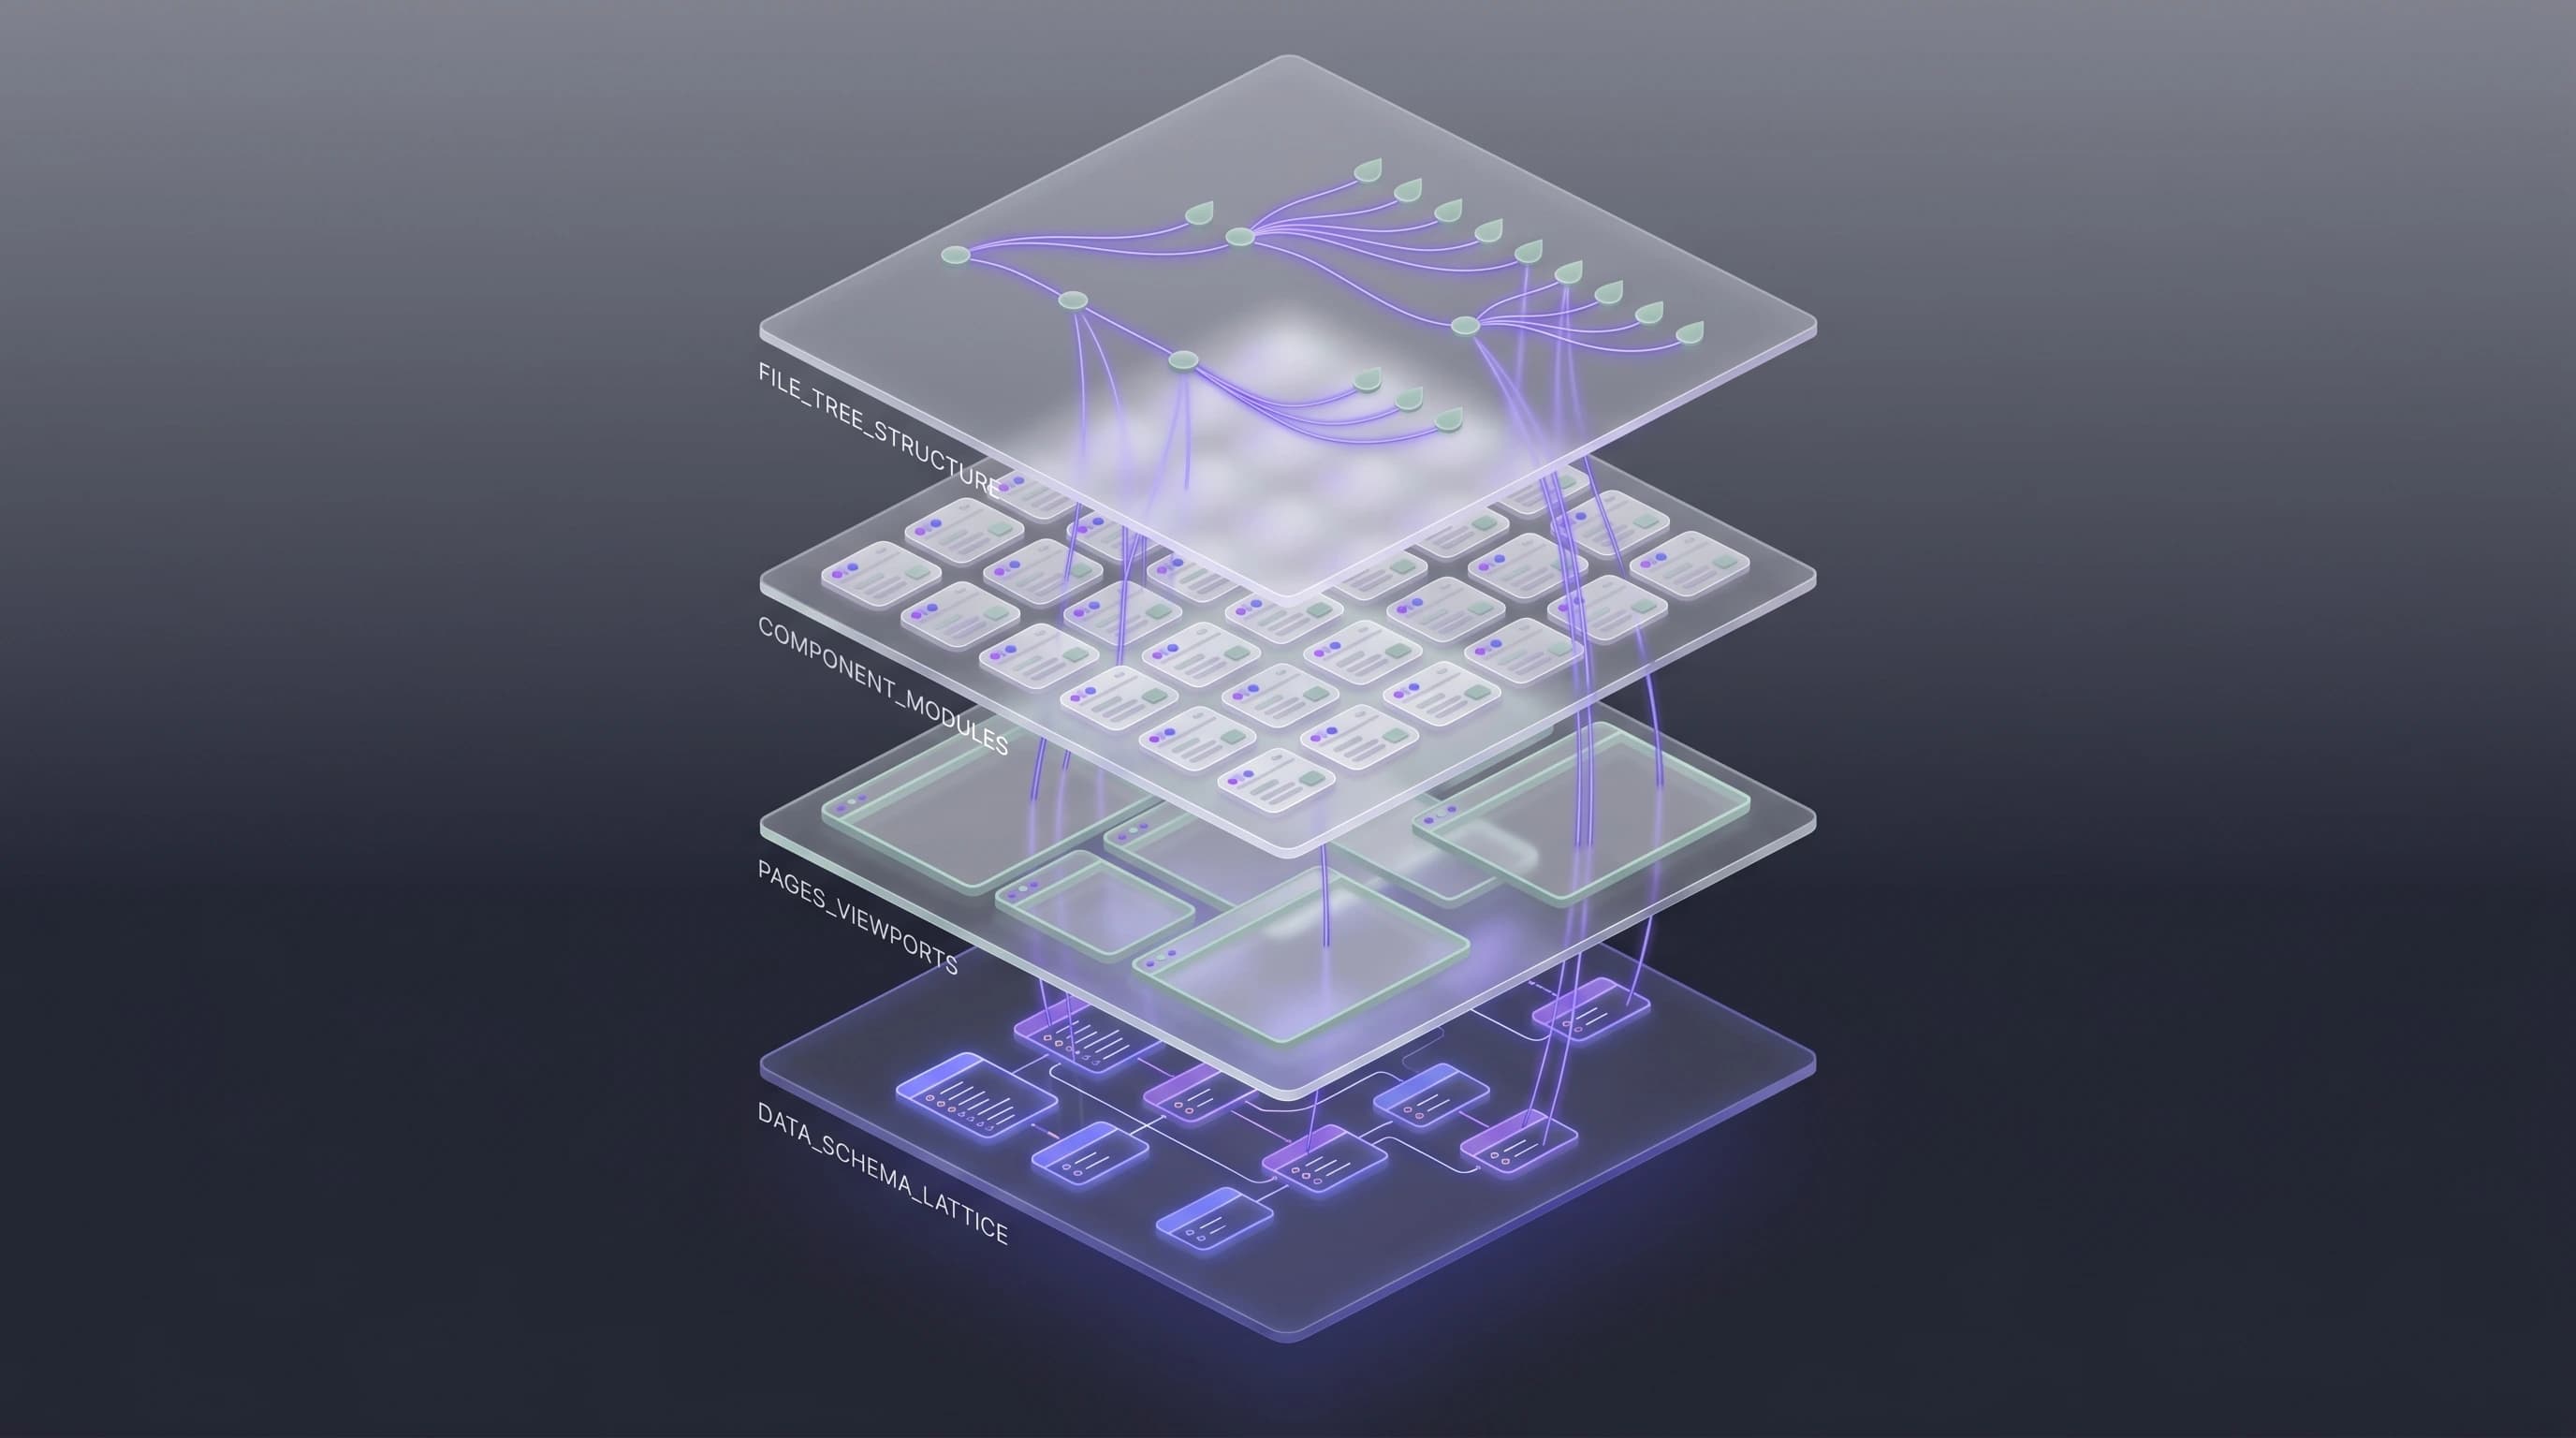
Four layers, in this order, and the order is the whole point.
- Schema. The data model comes first, because every entity in the app traces back to a table.
- Pages. Each page exists because one or more user stories requires it.
- Shared components. Extracted after pages are known, so duplication becomes visible rather than theoretical.
- File tree. Derived from pages and components, never invented.
Invert this, start with the file tree and work backwards, and you get exactly the broken scaffolding above. The tree is the final projection of decisions made in the earlier layers, and projecting before deciding produces a shape with nothing behind it.
Layer 1: schema
Until you know your entities, you cannot sensibly design pages or components, because you do not yet know what the app is about.
Given these user stories and features:
<PASTE STORIES + FEATURES>

Generate a relational database schema:
1. Identify every entity in the stories, including implicit ones
   like session, notification, and invite
2. For each entity, produce a table with column name, Postgres
   type, nullability, default, and primary key marker
3. Relationships: foreign keys with explicit ON DELETE behaviour,
   and junction tables for every many-to-many
4. Indexes: one for every column used in a WHERE, JOIN, or
   ORDER BY by a user story
5. Constraints: encode uniqueness rules stated in the stories as
   UNIQUE, not as comments
6. Audit trail: if any story mentions history or activity, add
   created_at and updated_at plus a versioning strategy

Do not store derived values. If a story mentions a computed figure,
note it as a query rather than a column.

Output:
1. A Mermaid erDiagram block
2. A SQL DDL block, executable against Postgres
Without those explicit rules, three things go missing every time. ON DELETE behaviour, which turns into a surprise in production. Indexes, which means the app works in development and falls over in production. And audit columns, which you will want the first time you have to debug something.
This layer deserves the most care of the four, because it is the only one that gets more expensive to change every day you are live. From user stories to database schema works a complete example end to end and covers the six mistakes worth reviewing for.
Layer 2: pages
Pages exist because stories need them. Generate pages without a story map and you get pages the app does not need.
Given these user stories:
<PASTE STORIES>

And this schema:
<PASTE LAYER 1 OUTPUT>

Generate a complete page inventory. For each page:
- Route, for example /dashboard, /projects/:id, /settings/billing
- Purpose, one sentence
- Which stories this page satisfies, by name
- Which schema tables it reads from
- Which schema tables it writes to
- Required role: public / authenticated / admin
- Required states: empty, loading, error, populated

Rules:
- Every story is satisfied by at least one page
- No page exists without at least one story justifying it
- Admin-only pages are grouped separately

Output as JSON array.
The "which stories this page satisfies" field is the load-bearing one. Requiring it means the model cannot produce pages with no reason to exist, because it would have to name a story that does not exist to justify them.
The required-role field is worth as much. An unguarded admin route is one of the more common and more dangerous outcomes of generated code, covered in why AI code breaks in production, and declaring the role at the inventory stage means the code generator has something to check against.
Layer 3: shared components
The trick to a clean architecture is naming the shared components explicitly. Without that, the model writes the same <DataTable> five times for five pages, because each generation is a fresh conversation.
Given these pages:
<PASTE LAYER 2 OUTPUT>

Identify shared components. A shared component is:
- Used by 2 or more pages, AND
- Has identical or near-identical functionality across them

For each:
- Name, PascalCase
- Purpose, one sentence
- Which pages use it
- Props with TypeScript types
- States it must support: loading, error, empty, populated
- Whether it accepts children or is a leaf

Rules:
- Aim for 8 to 15 shared components maximum. Over-abstraction is
  worse than duplication.
- Never promote something used by only one page
- For each, explain in one line why it is shared rather than duplicated

Output as JSON array.
The cap matters more than it looks. Asked for a component inventory with no ceiling, models promote every small UI element to shared status, and you end up with forty "shared" components of which twelve are used once. In a medium app, 8 to 15 genuinely shared components is realistic and anything beyond that is noise you will have to unpick later.
Layer 4: file tree
Now the tree, which is purely derivative of the three layers above.
Generate a file tree for a Next.js App Router project with these
pages and components:
<PASTE LAYER 2 + LAYER 3>

Rules:
- App Router conventions: app/[route]/page.tsx
- Shared components grouped in /components/<category>/ where
  category is one of: ui, forms, layout, data-display, feedback
- Server actions in /lib/actions/<entity>.ts
- Generated database types in /database_types.ts, marked as generated
- Manual TypeScript types in /types/<entity>.ts
- Hooks in /lib/hooks/<entity>.ts
- API routes only for things that cannot be server actions:
  webhooks, public endpoints

Every file path gets a one-line purpose comment.

Output as a tree structure with comments.
Stating the conventions explicitly is not optional. Without "App Router" and "server actions over API routes," models default to Pages Router patterns, because those dominate the training data by volume. This is a general property worth internalising: the model's default is the most common pattern in its training set, not the current best practice, and the gap between those two grows every time a framework ships a major version.
Shared components versus over-abstraction
This is the hardest judgment call in the whole process, and the one I see people get wrong most often in both directions.
Four anti-patterns worth rejecting:
A universal <DataTable>. Almost always wrong. A table abstraction that tries to serve every entity serves none of them well. Prefer per-entity tables, <ProjectsTable> and <UsersTable>, sharing smaller primitives like <Pagination> and <SortableColumn>.
A universal <FormField> wrapper. Every form has different validation, different error handling, different accessibility requirements. A single wrapper becomes a soup of conditional props within about three forms.
A <Modal> owning its own open state. Makes shared usage fragile in ways that are annoying to unpick. Prefer controlled modals where the parent owns state.
A <Layout> doing both site chrome and route logic. Split it: <SiteHeader>, <SiteFooter>, <AuthGuard>, each with one job.
The test I would apply: would a new engineer joining the project understand when to use the shared component and when to duplicate? If the rule is not obvious, the abstraction is wrong, regardless of how much duplication it removes on paper.
File-tree mistakes to watch for
Everything in one flat /components directory. Fifty files in one folder is unnavigable. Group by category.
API routes duplicating server actions. In App Router, server actions handle most mutations. API routes are for webhooks, third-party integrations, and public endpoints, not for CRUD.
/utils/ as a dumping ground. Past about five helpers, split by domain, or it becomes the folder nobody wants to open.
/types/ duplicating /database_types.ts. Generated database types never live in /types/, and manual types live only there. Mixing them causes drift that TypeScript will not catch, because both files compile fine.
Tests in a separate /tests/ tree rather than co-located. Co-located tests scale better and produce fewer orphans when files move.
Doing this by hand
Running all four layers manually for a medium-complexity product takes two to three hours. The intellectual work is not the hard part. The bookkeeping is.
Every manual paste is a chance to break the chain. Miss one persona when you copy stories into the schema prompt, and the schema references an entity that no longer exists anywhere else. You will not notice until layer four, and by then you have to redo layers two and three as well.
That is the honest argument for automating it. Not that a pipeline prompts better than you would, but that it tracks what depends on what, so editing a story flags the schema and pages that referenced it. VibeMap runs these four layers with that state persisted.
Related reading
- How to generate an app spec from a prompt, the full seven-stage pipeline that this is the back half of.
- From user stories to database schema, layer 1 in depth, with a complete worked example.
- Why AI-generated code breaks in production, the failure modes this ordering is designed to prevent.
- AI acceptance criteria, what to generate before you get here.
To start with the layer that matters most, the Database Schema Generator turns user stories into an ERD and PostgreSQL DDL. Free, no signup.
Sources and further reading
- Next.js, App Router documentation: the canonical conventions.
- PostgreSQL, Data Types: the right types to use, and why TEXT is rarely the answer.
- Robert C. Martin, Clean Architecture: the layering principles behind the ordering above.
- Martin Fowler, Patterns of Enterprise Application Architecture: component-level abstraction guidelines.